The Moment Everything Breaks at Once
I was three years into my job at a mid-sized financial services company when our main trading platform decided to have what I can only describe as a spectacular nervous breakdown. It was 2:47 AM on a Tuesday when my phone started buzzing with alerts. By 3:15 AM, I was staring at a terminal screen showing cascading failures across systems that hadn’t been properly maintained in over five years. The authentication service was timing out, the message queue was backing up, and our primary database was struggling under a load that should have been routine.
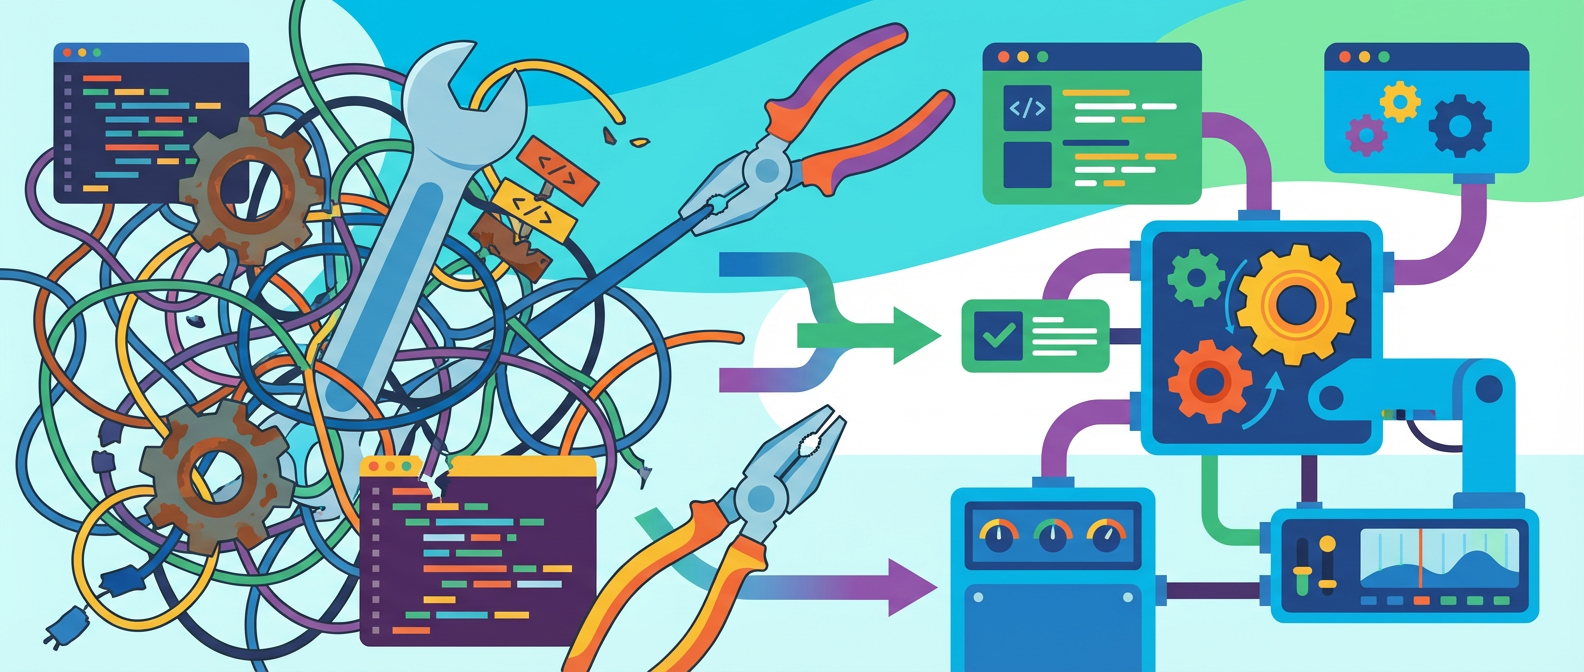
That night taught me more about technical debt than any conference talk or blog post ever could. We had inherited a system built by brilliant engineers who had made reasonable decisions under tight deadlines. But those decisions had accumulated interest over time, and we were now paying the full cost. The quick fix that saved two weeks of development time in 2018 was now costing us millions in downtime and emergency engineering hours.
Technical debt isn’t just about messy code or missing documentation. It’s about compound interest on deferred decisions, and like financial debt, it can either be managed strategically or it can destroy you. After a decade of wrestling with legacy systems across three companies, I’ve learned that the difference between manageable debt and system-killing debt comes down to how you measure, prioritize, and systematically address it.
Building a Debt Inventory That Actually Matters
Most teams approach technical debt like they’re cleaning out a garage. They know there’s stuff they should probably throw away, but they’re not sure what’s actually valuable and what’s just taking up space. My first breakthrough came when I stopped thinking about debt as a binary good-or-bad classification and started treating it like a portfolio of investments with different risk profiles and return characteristics.
We built what I call a “debt register” using a simple spreadsheet that tracked what was broken and why it mattered to the business. Each entry included the system or component, a brief description of the issue, the estimated effort to fix it, and the business impact if we didn’t fix it. We sorted debt into three buckets: performance debt that was slowing down development velocity, reliability debt that was causing production issues, and security debt that was creating compliance or safety risks.
The key insight was measuring debt in terms of developer-hours lost per sprint, not just in terms of how ugly the code looked. That authentication timeout issue? It was costing us roughly 12 hours per two-week sprint in debugging time and workarounds. The legacy data migration script that required manual intervention? Another 8 hours per sprint. Suddenly, we had a business case for prioritization that made sense to both engineers and product managers.
We also started tracking what I called “debt velocity.” How quickly new debt was being created versus how quickly we were paying it down. This became crucial for understanding whether our current practices were sustainable or if we were heading for another 3 AM disaster.
The 20% Rule and Why It’s Not Enough
Every engineering team has heard the advice to spend 20% of their time on technical debt. It sounds reasonable in theory, but in practice, it often becomes the thing you skip when deadlines get tight. I learned this the hard way during a product launch where we deferred debt work for three consecutive sprints to hit a marketing deadline. Those three sprints of deferred maintenance turned into six months of reduced velocity and increased operational overhead.
The problem with the 20% rule is that it treats all debt as equally urgent and equally valuable to address. In reality, debt follows something closer to a power law distribution. A small number of debt items create the majority of your pain, while most debt items are relatively harmless. The authentication service issue I mentioned earlier was probably responsible for 60% of our operational overhead, while dozens of minor code quality issues combined barely moved the needle on developer productivity.
What worked better was implementing what we called “debt sprints,” dedicated periods where the entire team focused on a single high-impact debt item. Instead of trying to nibble around the edges of multiple problems, we would take one week every quarter to completely resolve one major piece of debt. This approach meant we could actually eliminate problems rather than just maintaining them at a barely-tolerable level.
We also established debt thresholds tied to specific metrics. If our test suite took longer than 10 minutes to run, fixing that became a P0 priority. If any single system was responsible for more than 30% of our production alerts, that system got an immediate debt sprint. These thresholds gave us objective criteria for when debt had moved from “annoying” to “business-critical.”
Refactoring vs. Rebuilding: Making the Hard Choice
The most expensive mistake I’ve seen teams make is trying to incrementally refactor systems that should be rebuilt from scratch. There’s a psychological trap here: refactoring feels safer and more predictable than rebuilding, even when the numbers clearly show that a rebuild would be faster and more reliable.
I faced this choice with a customer notification system that had grown from a simple email sender into a baroque monster handling push notifications, SMS, webhooks, and three different email providers. The original system was built around the assumption that we’d only ever send a few hundred notifications per day. By the time I inherited it, we were processing over 50,000 notifications daily. The system was held together with caching layers, circuit breakers, and a lot of prayer.
The refactoring estimate was six months of careful surgery to extract interfaces, add proper error handling, and implement horizontal scaling. The rebuild estimate was four months to create a new system with proper architecture for our current scale. The refactoring felt safer because we could deploy incremental changes and roll back if something broke. But the rebuild was actually less risky because we could build and test the new system in parallel with the old one, then cut over when we were confident it worked.
We chose the rebuild, and it was the right decision. The new system was simpler, faster, and more reliable. More importantly, it was built with our current scale and requirements in mind, not trying to accommodate decisions made when our business was fundamentally different.
The framework I use for this decision is based on what I call the “foundational assumptions test.” If the core assumptions underlying a system’s architecture are no longer valid, refactoring is usually throwing good money after bad. If the assumptions are still sound but the implementation has gotten messy, refactoring is often the right choice.
Building Systems That Accumulate Less Debt
The most effective debt management strategy is prevention. After watching multiple systems accumulate debt in remarkably similar ways, I’ve identified a few architectural patterns that seem to naturally resist debt accumulation.
The first is what I call “explicit error boundaries.” Instead of letting errors bubble up through multiple layers of abstraction, we started designing systems with clear points where errors are caught, logged, and handled. This meant that when something inevitably breaks, the failure is contained and debuggable rather than creating mysterious cascading effects that take hours to trace.
The second pattern is designing for observability from day one. Every system we build now includes structured logging, metrics collection, and distributed tracing as first-class concerns, not afterthoughts. When performance starts degrading or errors start occurring, we have the data to quickly understand what’s happening and why.
The third pattern is building with operational complexity in mind. We started asking questions like “how will we deploy this safely?” and “what happens when this service is down?” during the design phase, not after we’d already built something that was difficult to operate. This led to simpler architectures with fewer moving parts and clearer failure modes.
These patterns don’t prevent all debt accumulation, but they do create systems that degrade more gracefully over time and are easier to modify when business requirements change.
Managing technical debt is ultimately about building the muscle memory to make small, consistent investments in system health rather than waiting for catastrophic failures to force your hand. The teams that do this well treat debt management as an engineering discipline, not a cleanup activity. If you’re dealing with similar challenges in your systems, I’d be curious to hear about what strategies have worked for you and where you’ve seen approaches break down.